Off the Top: Information Aggregation Entries

20052010201520202025

Showing posts: 1-15 of 142 total posts


22 September 2026

Modernized Page Structure for the Model of Attraction Draft from March 2002

I’ve been looking at filling in the gaps around the Personal InfoCloud and setting the foundation for it in the four InfoClouds in an Overview of the InfoClouds, but pointing back to a quick framing of the Model of Attraction, mostly leans to the original draft (and only a first draft) of the Model of Attraction - First Draft :: vanderwal.net that I wrote on a flight back home from Austin when the idea hit.

Looking at that page, the page was still in a 2002 or 2003 layout and design, which is quite similar to what it is today, but the text was much smaller and the page much narrower.

Update of the Layout Structure

I updated the layout structure of the page and the HTML framework of the page and used the current CSS that does much of the layout work (then and now). I also fixed a few typos and corrected the date at the top, which was a year off as stated elsewhere, as March 2002 is the correct date.

I Haven’t Read Through This In a Long While

As I was resetting the scaffolding of the page I realized it has been a long time since I have read this in full, and I need to set aside time to do that. There are quite a few things I wrote out fully in the rough draft and in the outlined sections at the end, which set the foundations for much that was to follow. But, it goes much farther in a broad sense pulling things in and building bridges to uses of the model within different domains that people work in. The initial piece also calls out the initial rough use of info cloud in my quote:

“Users have a rough cloud of information following them that has a magnetic attraction toward them and their interests.”

I had forgotten about that. It had been captured by someone I was talking with as the idea was gelling and I used it a couple of times and realized it had gravity. This became the hook for InfoCloud.


16 September 2026

I Wrote What?

Part of the impetus for writing this post has been driven by the updates at A new Observable | Observable, which I recently wrote about Large Observable Update :: Off the Top :: vanderwal.net, and looking at changes in not only Observable, but updates to D3 by Observable. These current and not-too-distant updates have had me thinking about what I could do with some of my blogging data to make interactive charts and graphs. I’ve recently moved a lot of my legacy static charts and graphs to Plotly to gain interaction with them, for many of my own uses. But, in the process of getting a decent data workflow setup for my site (and my notes data) I have relatively clean data locally ready for use and testing.

A Little Data Workflow Background

For this blog I have been pulling down the data from the site’s backend and converting it with a set python script to extract it to SQLite, which is relational but quite fast for reading data and is great for single user write and a few read options. Over the past few months I’ve also been building many data analytics and data visualization prep python scripts (some building JSON files for standalone webpage interfaces). I’ve used Claude to debug, but also just turn out a script in less than couple minutes for the page setup for the D3 or Plotly scripts, which would usually take me 30 to 120 minutes. Once the scripts are set and I’ve reviewed them it is all just setting python flags and minor tweaks to the script to handle a data update.

With these script setups I’ve been able to try quite a few D3 chart and graph options very quickly. Going through the Python code, the data structures for the visualizations, and the hooks for the visualization and I’m rather happy with it for quick outputs.

What Can I See Using Blaugust Data

One of the things I had interest in from my A Wrap to Blaugust / Blaugust run in August was what did all of that look like from a basic statistic and graphical perspective. A few months back I created and ran a bunch of Jupyter queries and visualizations, Personal Blog Data Analysis - Looking at 25 Years. Since then I’ve been thinking about looking at a monthly view with more interactive charts and graphs. Since I had a decent amount of data from August 2026, existing data workflows, and a few D3 charting and graphing options I could work with I took a look.

August Off the Top Force Graph

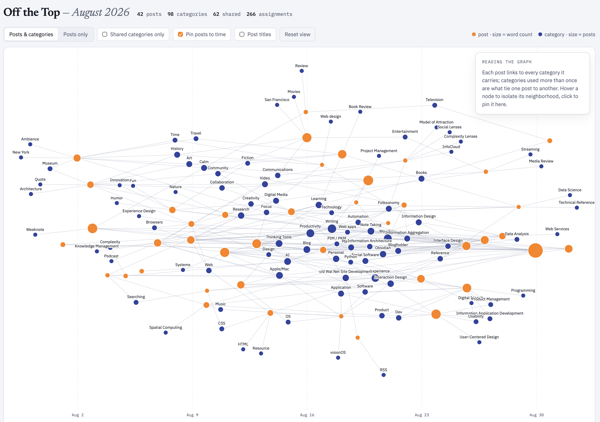
The first is an interactive forced graph with the blogpost as orange nodes with the size corresponding to word count and the tethered edges link to categories for the post. Clicking on the post will show the related categories and pulling on the post node will start to see the other tethered posts connected through the categories. There are few toggles: 1) Posts and categories or just Posts with their related interconnections; 2) Only show shared categories (a category with more than one post); 3) Post to Time, which may be my favorite view, as it take the graph and lays out the posts left (oldest) to right (most recent), with a small light timeline at the bottom and all the other relationships displayed as well; 4) Post titles, which clutters things a bit and adding the toggle resolved that clutter.

You can view this standalone interactive web chart that sits in the Lab :: Off the Top Analytics at the direct link: Off the Top, August Force Graph with Toggles. A sample is here:

A forged graph chart image showing August 2026 posts and connected categories

August 2026 Word Counts

As I was going through the data for August 2026 I knew and could see the word counts for posts, which I don’t have easily (nor quickly) available on my site. But, with the data local in SQLite and I’ve been using the local data to run many types of post analytics, word counts become a simple and quick option that doesn’t impact the site’s performance at all.

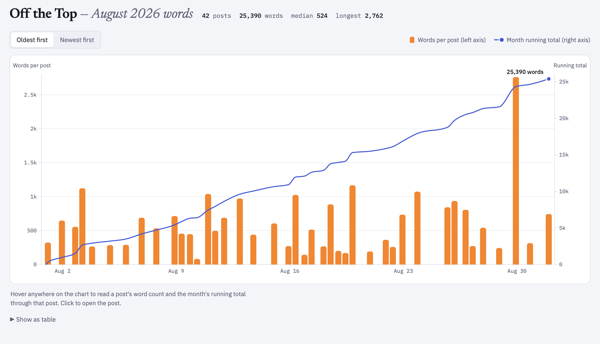
I was really curious about word counts per post across August, but also was more curious about a cumulative word count across the month as well. A quick and easy bar chart and line graph solved this, both having interactive hovers for metadata. August had 25,390 words posted.

The standalone interactive web chart is also in the Lab and the direct link is: Off the Top, August Word Counts by Post and Cumulative Count. A sample is here:

A bar chart image of monthly posts with height correlating to word count and a line above the bar chart showing cumulative word count for the month August 2026 posts

Cumulative Word Count for 2001 to 2026

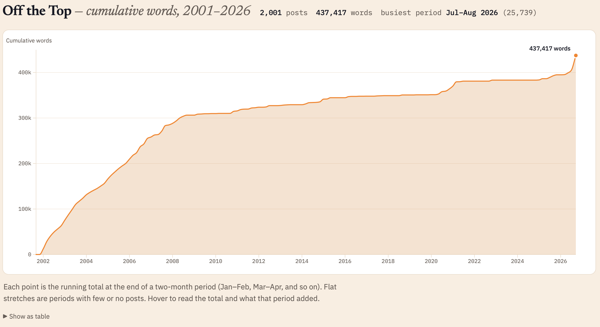
Looking at the cumulative count for August 2026 (the 25,390 words posted in the month) I had no idea what that count was in comparison to the whole life span of the blog (under this CMS that started in late October 2001 and not including the static posts prior to that). I know that in the early months and years of the blog I wrote a lot of short posts and the posts were frequent. Looking at word count I wasn’t expecting the first two or three years to have roughly the same growth slope up to 2008.

Looking across 25 years of posts I knew a single post analysis was going to be a bit rough for an interactive standalone webpage. Monthly would be better, but could still be a bit too much to process dynamically in the browser. Quarterly, was just a bit on the thin side and more difficult to see trend shifts and correlative line slope. I settled on a two-month interval and I had something interesting in under a minute.

July and August 2026 were the highest word count across all time on this blog. The 25 thousand words is roughly a quarter of a 250 page book. But, now that I had the bi-monthly chart I can also see the early years I had roughly similar counts per two months up until 2008 and then there was the “great flattening”, until the “great pandemica” lockdown when things ticked up again until lockdown ease and work went back to its normal patterns.

I ended up over the 25 years with 437,417 cumulative words just on this blog. That is roughly 4 books of 250 pages. It would be a rather odd book, but in just considering word count as the focus. I find word counts odd, particularly writing to word counts. I’ve had a regular column in tech publication that had a 750 rough word count topic, this was at a time when my posts were often 1,000 to 1,250 words on average and 750 words was about where I had the framing set to get to the meat of things. I mostly write on this blog to an amount where there aren’t good words left, which is 200 at times to 2,500 or more. To see my writing shifts in the early years roughly similar in trajectory rather interesting.

The standalone interactive web chart is also in the Lab and its direct link is: Off the Top All-time Cumulative Word Count. A sample is here:

A line chart showing cumulative word counts across 25 years of blog posts

Will this Continue?

Now that these are standalone webpage charts and graphs, I’m not sure what I will do. I need to get the templates consistent from a layout and design perspective. But, once the standalone webpage is created I just copy it to the Lab or other location, and this can be automated with a quick script. I think the month-by-month analytic is interesting, at least to me. I have not only the local standalone version that I posted, but a rough output build that isn’t fully self-contained that I can play with and iterate on.

If you like this and want to see more ping me on one of the services or send an e-mail using the Contact in the navbar.


27 August 2026

Zeef Returning

One of the things that has been bringing enjoyment lately is seeing ZEEF coming back to life. It self-describes as: “Curated links, found by algorithms, sifted by people”. I’ve used the new version and have found it more responsive and a bit easier to use.

I have set up a curator page in the new Zeef at Thomas Vander Wal | ZEEF. If you are new to Zeef and didn’t catch it the first time around, it is a different perspective on saved and shared links. Where things like Delicious and Pinboard focus on an abundance of links which the users tags as they go, which provides a folksonomy / folksonomy - defined of terms from the bookmarker’s output, Zeef has a focus on categories on a curator’s page and the links the curator believes are appropriate for that term. From a folksonomy perspective the person adding the tag / category is very clear (which is essential), the group of links has the category, and the links are the objects being tagged / categorized. Different people have different perspectives as we each have multiple contexts from our lives and everybody has a unique set of those contexts.

This early resurfacing of Zeef is still a work in progress, but has some nice new additions. One of the pieces I like is, curators having the option of adding a “why” to the links for a term. This “why” I find valuable as knowing why a curator added a link to their collection provides increased value for those reading the collections. On my page I have started a category collection for folksonomy and I’ve captured an initial three links in the section and I’m showing an expanded the entry for the Ontology of Folksonomy (from Tom Gruber) that shows the “Curator’s Note” and the “Why” reasoning I added. The Curator’s Note provides a definition opportunity and there the link fits, whereas the “Why” is the curator’s insight as to why they believe it is worth including.

Prior Zeef Mentions

The first version of Zeef was something I enjoyed, but didn’t take full advantage of, but I had ideas of how to expand my curated sets. I was looking at it for how to handle Blogfodder and Linkfodder. I also was thinking it could help with managing What to do with Podcast Favorites.

Looking Forward to Zeef As It Move Forward

This new version of Zeef is something I am looking forward to seeing grow and get used again. I think there is a place for having solid curation of links and resources. I’ve been thinking about how Zeef could be the community space to find resources centrally, like things captured on people’s personal sites in their slash pages (slash pages) which they keep on their site, but have a place to discover centrally.

I also really like the idea of having researchers and professionals curate their list of categorized resources. One thing I really enjoy this time of year are syllabi for courses and to see reading lists for new sources, but also how professors frame the accretion of understanding build over a semester (for those professors that share these openly).


25 August 2026

Adjusting Daily Aggregation for Less Friction

Sunday I hit a point where my daily automations (which I layout in part here - My Automations Over the Ages and Today’s View in my morning process and weekly process) and placing the outputs into my Daily Dump note sections was really making for a lot of friction in my note taking / note making. Additionally, it was breaking focus and holding my concentration on what I was trying to capture in my note’s sections.

How Daily Dump Notes are Setup

My Daily Dump has 14 sections: Plans, Thoughts, Review, Read, Talked With, Listened, Watched, Productivity, Worked, Learned, Played, Ate, Health, Bought, and Added to a wishlist.

The intent with the subheads in my note is to quickly jump to the section as I run across something or am thinking through and idea or concept and capture the thoughts or what I consumed and ideas from it, so I can get back to it later in my notes. But, since this is markdown and in Obsidian I can take the notes with its subheading and text, extract it, and then transclude it (move it out and link it back in to show it in another note). But, having each day’s note relatively clean (the exception is the Plans section for things brewing and on the front burner to do are moved from the prior day’s note to the current day’s with a python script that keeps the completed tasks on the prior day and removes things not completed and moved them to today).

Friction from Adding Aggregation to the Sections

The daily aggregations pulled in things captured from various reading and copying or favoriting tasks that get automatically captured in Instapaper and Pinboard, as well as all the files I created and modified. I also have notes from Drafts that I capture on the go and tagged to get pulled in aggregated, as well as a list of things I watched online that I want to track, but also list of videos watched where I’ve captured the transcript in Readwise I may want to review (and likely do a further clean-up step).

All of this was getting aggregated into collective notes by type and transcluded into the relevant groups in my Daily Dump note. This added a lot of friction to the intent of my Daily Dump for quick easy drop into a section and capture a note and then after sort out how I may handle it. Add to this, Sunday my Weekly Review runs and captures all of this from the week and compiles it into one note so with a heat map at the top so I can review it to see what I’ve been doing and find things to cut back on or put focus on for the upcoming week. The Weekly Review was transcluded into Productivity, which is ironic as all of this adding of aggregation transclusions was making me really unproductive.

The Fix to Bring Back Focus and Quick Capture

On Sunday I had enough of the friction and took time to sort out a solution. I liked the capture and the ability to scan through and find things I need to continue working on or make a change on, but having it in my quick capture notes area made it tough.

I added a “Review” section just under Plans and now all aggregations and transclusions go there. The best part is when I’m not reviewing it, a heading in Obsidian can be collapsed, which gives me focus on everything else.

On Sunday I did a quick manual restructuring of my note by putting everything aggregated into the Review section and then collapsed it. This was a magical focus trick.

Updating the Python Script that Automates Transclusion

Sunday I did the first edit of the python script that takes the aggregations notes created earlier in the moring and transcludes them in and repointed them to not go into the other categories, but all go into Review. This hasn’t run perfectly yesterday nor today (it works when I trigger it to run manually, but not from the trigger to run the script), but it is getting closer.

Protecting Focus is Key

Protecting focus and being able to quickly shift focus and be productive is key and has been something I’ve been working to do since I was a kid. Over the years I’ve learned the distractions and how to pull focus and calm back in. Removing the friction from abundance of information already in where I needed clean space to quickly capture created the large problem.

Now my big next step is sorting out the time to actually get a good weekly review done from what I’ve aggregated. The capture has been really good, but I just need to get better about protecting time on Sunday (or move this to Saturday) so I can sit and focus on what was done, what I can reduce and what needs focus to get done.


21 August 2026

Fragile Automation Systems

I have a set of early morning aggregation automations I run and in the last few months I’ve run into oddities with regular automated syndication of data streams. I have quite a few things that push to a Slack channel, but it something keeps changing with Slack and it isn’t capturing anything. Much of it seems to be on the Slack end of things where inbound connections route to a Slack bot and not to the hardwired channel in the instance.

Slack used to be the stable and solid endpoint for tracking data, but something has changed.

I have a few different services that have triggers for automating capturing, copying, and writing data in another service where I can more easily make use of it through pushing it to a calendar, spreadsheet, central messaging (where I control when I pay attention to it), and moving it into a format for review or to work with on some calm cadence. Slack is one of the calm endpoints, and sometimes midpoint where I pull certain things in the last day or two from Slack to be in full view with other related items working around.

My keyboard shortcut app of choice for more than a decade has been hitting odd security lockouts that keep it from working. The lockouts are from other apps or services and they lock it from working across the device. I have around 15 to 20 shortcuts I use regularly to insert templates, drop in URLs, add dates, and more. But, when it gets locked I type the three or four keystrokes and nothing happens. It is like being in a dreamworld and a door won’t open. After an hour or few the lock goes away and it works. I’ve contacted the vendor and they are trying to sort out what is now causing this.

When then the automations and silent systems break or an interface is empty, but should have quite a few things in it and there are only a few, it is a little disconcerting. Fragile services aren’t new, but many solid services for years are now increasingly fragile and that trend needs to reverse.


10 August 2026

My Automations Over the Ages and Today’s View

For a few decades I’ve converted regular manual tasks into automated tasks for many things. I use short code keyboard conversions with TextExpander (TextExpander), Alfred (Alfred), Keyboard Maestro (Keyboard Maestro), Hazel (Hazel by Noodlesoft), Apple Shortcuts, and a couple other small apps and services. But, I also have quite a few scripts in python and Ruby, but a few pure bash scripts. I have a handful of apps that use Claude Cowork (Claude Cowork | Claude by Anthropic) on a schedule and used where the data is not always standard, so it aggregates and structures the data where it often later gets processed by python.

I started building and running automation scripts in the 1990s to handle tedious tasks with multiple steps, or would likely be victims for typos, and which I was handling daily. A task that would take 3 or more minutes (often longer) and had structured stable data I could search made it viable to become a script and automated. I had them to filter email to folders, filter downloads to common folders / directories, and one to turn off audio for the evening which monitored Twitter every 30 minutes for my nightly signoff (“off to read and sleep - zzzz”) and it would mute audio. I’ve had a few for audio that would capture podcasts I was on for a local copy during recording that took just one button click to set Audio Hijack Pro properly and it just worked.

Moving to the Current Adaptive Flows

The last six months (or a little more) I’ve been building aggregators to capture what I’ve done the day before (and the week prior for a manual review). I’ve also automated my morning Obsidian (Obsidian) setup, so that my daily note (or Daily Dump for my notes, in my vocabulary) templates are created for the week ahead with a python script, rather than creating a new note and use a TextExpander snippet to build the structure each morning. But, doing this I realized that I could take my daily task list and the list of potential tasks I keep at the top of my Daily Dump and script the moving uncompleted items to that day’s Daily Dump from the day prior, but also quickly run a calendar scan for the day with Claude and the BusyCal MCP to have my known items at the top of the note written directly in the note. The completed items and checked off were left on the prior day’s Daily Dump in their sections.

In order to run the scheduled python scripts I need my laptop to be awake in the background (but it still the screen remain locked) so to run early morning tasks. I found PMSET as the key to handle the wake-up for the first run and have a python script handle the remaining wake-up processes for that day.

I now have a mix of Claude Cowork Skills (which if I sort out the data is stable enough I convert them to python for consistency, speed, and sustainability) and python scripts that pull my prior day’s files created and worked on list, my items in a feed of the prior day’s additions to Instapaper, Pinboard, and a list of new items in DevonThink as PDF (with links to the PDF as well as a working URL to the source of the item), a list of Readwise articles and video transcripts, and videos I liked and sent to my personal instance of Slack. These lists are in markdown and placed into the directory Obsidian watches over. Most of them a little later in the morning are transcluded into my Daily Dump note for the day where I read through them.

Morning Process

My morning process is to read through what was done the day before and edit them to add links to other resources in Obsidian and write notes. Often I have some entries that will turn into that day’s list of things to do or one of the “potentials” list. I will take items that need to be their own item note or be included into a concept note. This keeps the items fresh on my brain and connecting things to where I can get back to them more easily.

I write this today, as this morning I found my morning automation hadn’t fully run properly, because my Sunday evening script to create the week’s Daily Dump notes didn’t run as it was a cronjob and I was cooking with the laptop asleep so the job didn’t kick off. This morning I converted the cronjob to a launchd task instead and to run on Sunday during another automated wake open window.

Weekly Aggregation

Sunday’s I also run a weekly wrap-up, that pulls everything done for the week. I’m finding this is a bit too much information for a quick review and a manual assessment for the week where I aim to map out things for the upcoming week. It is a bit too much information overload. I don’t know what I’m going to do about it. Now that I have things automated and aggregated I need to rework my human side of things.

The Value of the Automation

The goal of my automations is to give me time back and remove the manual and grunt work so I can do the thinking work. I’ve done this with personal life and work life (and large systems and projects). The current round of automation and aggregation surfaced that I am doing more than I thought I was doing. Another goal is to give more time to do the human thinking and the projects and work needed. I do this so I can do the creative human work and the human thinking work (I find large errors in summarization in nearly all generative AI and creative work so I keep that at bey and use it for grunt work that I check). The scripted automations don’t need the hand holding and I have some occasional test run to check on them to see if they need attention and honing.


3 September 2022

Weeknote - 3 September 2022

You are asking, “Where are you? Are you okay? Are you still blogging?”

In TikTok parlance, “Great questions. Let me tell you.” First, this standard TikTok pattern is one I find really interesting. It fills in he politeness / nicety gap that has become common in the last decade or two, where people jump into answering questions. This nod to thanking the person asking encourages questions and puts people at ease who asked a question (speaking up is often not something most people are comfortable with). But, the pattern has been used so much and is just a common / required custom, it starts to come off as forced or canned, much like required legal disclaimers. None-the-less, it is a good practice.

Well this was a long “week” (parts of this were in an end of March weeknote that needed finishing, so now edited and updated). Things on the work front got incredibly busy and hectic. I’m going to treat this “weeknote” as a catch-up of things that have held my attention over the past year.

I’m hoping to get back to posting regular weeknotes and blogging. My other blog Personal Infocloud has been quite for a long time, but been waiting for about 2 years for SquareSpace to fix a defect that impacted styling and showing full posts. I have a lot of older content I’ve long used in presentations and workshops, that I’m working to turn into videos of some of the pieces of them that are clearer for understanding in video / animated form. I’m also back working on the 70 plus set of social / complexity lenses I’ve been working on for around 14 years with that label, but around 20 years all together going back to the Model of Attraction (still a foundation for a lot of thinking and framing).

With my son off to college, I may have a little more time to write and share. I’m also looking at a digital garden model (see the last section) and as of recently Massive Wiki for a collaborative or commons approach of moving the Lenses forward (well outward).

Note Taking

I have been deep into cataloging, reading, and using the heck out of Obsidian since trying it out in June of 2020 and going all in at the end of July 2020 and it is now second nature. But, this built on my 10 or so years of taking markdown notes in a directory, which I had 8 to 10 year of text notes in that same directory (which were bulk renamed to markdown). My approach and use of aliases and front matter have changed how I do things, but more on that in the Productivity section below. Many of my issues in a quick test of Roam proved to save me from that path and set of problems, Notion not being mine and not a standard file format so I can reuse the notes easily has stopped being used, I use DevonThink but its backlinking and attempt at other Obsidian functionality was clumsy in my source archive (and I just pull in my directory that Obsidian sits on top of so search is relevant with resources saved), and with Obsidian now having iOS capability I’m really using it a lot on the go. I have a seriously strong preference for having the notes be separate from a system that wrangles and provides organizing for and around them. Having used nvAlt for nearly 10 years when it broke badly and wouldn’t open, all of the 2,500 or so markdown (and text) notes that sat under the app in a directory (and linked with file metadata tags). Putting Obsidian in the same notes directory and crating that directory as a vault things just continued on, but now with far more functionality.

One irony is my use of Obsidian, and in particular my daily notes (Daily Dump), has me posting and sharing here less. It is ironic as I write in the Daily Dump as if I am writing to others, but the notes are just to myself (for now - this may change if I can sort out how to keep some of the reading, learning, observations, etc. separate from work or formative observations. The Daily Dump was partly intended to capture things that could be shared back out in a weeknote. Things like the Personal Operating System, which I found insanely insightful (read below), things from Sentiers and The Near Future Lab (particularly around Generalists, which I find quite similar to a bumping into a brightline for polymaths, but also bumps up against Jane McConnell’s book The Gig Mindset Advantage (more on these later as well).

With Obsidian having tags (used to aggregate related things, as a hook metaphor I’ve used for 18 years or more) and the backlinks to use as bridges to move to related materials and ideas much in the way any hypertext environment functions. I used VooDoo Pad on my Macs for roughly 15 years, but it not easily working across iPad and phone to easily read, edit, or add to the corpus had it shift out of my main workflow. I also use Drafts for quick input from mobile and sometimes iPad.

Obsidian has been amazing with its pace and quality of development over the last 2 years. The iPad version is pretty solid, but I’m usually in reach of my iPad so I’m not leaning on it all that much at the moment. This past week there were large changes to the insider build for 0.16 (it was reworking some underpinnings to improve many of community built plug-ins, themes, and templates), but it was the first time the updates broke things in my workflow rather badly. Normally updates cause no problems, but only offer benefits and improvements, with occasional bumps that are resolved in 5 to 10 minutes. But, with the bump this week, I still love it for thinking through writing and note capturing and interlinking. There isn’t anything out there that is close to it.

Read

I have been reading a lot, with a good portion coming through me trusty RSS feed reader, NetNewswire, which echoes my vanderwal.net links page.

Newsletters

While I am not a huge fan of newletters (mostly the part that they arrive in email and not RSS, but the ones that also have RSS feeds are the ones I have been sticking to). Many of these arrive on Sunday, but I really wish it were Friday night or early Saturday morning so I have Saturday and Sunday mornings to get through them and follow the links and devour what is there, but Sunday mornings many arrive and I spend the week going through them.

The one that I am a huge fan of from a general purpose is Patrick Tanguay’s own newsletter Sentiers, which I find to be a real gem. I lost track of Patrick for a while after his Alpine review stopped publishing. I would love to see his Sentiers grow to be a bit more as I find it to be such a good offering. I have been reading it regularly for about a year or a bit more and Patrick has been popping up on podcasts I follow (Near Future Lab (now mostly moved to a Discord for and The Informed Life - more on these later).

Jorge Arango’s newsletter, Informa(c)tion, is an information and organization focussed gem that arrives every other Sunday. There are always good pieces and the links are gems.

Others I really enjoy and tend to link to things that open more browser tabs are: The Marganilian by Maria Popova; Curtis McHale’s PKM newsletter; and Monocle Weekend Edition newsletter (there are many times of late were the newsletter is a bit off target, but the balance for me mostly entertainment).

Books

The Gig Mindset Advantage has been a gem, mostly as it is very familiar as it is pretty much my natural (unintended) MO (modus operendi).

The Map of Knowledge, by Violet Moller has become one of my favorite books. It quickly turned into a slow meditative read as it broke some of my prior understanding of the world of knowledge and creation of advanced math, sciences, and philosophy. This refactoring of my understanding was around the realization that most of the “great books” and works that are the foundations are just very tiny slivers of knowledge that made it through an insanely fragile process of keeping paper copies. A book would need to be hand-written to create a copy and that copy on paper would only last 50 to 80 years before it would heavily decay. I knew well that most of what Western Europe used as fodder in the Renaissance for advancement were works from ancient Greece that had been kept alive through the great libraries and education systems in Persia, Near East, Middle East, Arabian regions, North Africa, and Moorish efforts in Spain. The realization that were may not be looking at the best thinking from the “classics”, but just those that made it through time.

While I had a decent understanding of the vast contributions advancing math, sciences, medicine, and philosophy that are the foundations of much of western thinking, I didn’t know much of the who, when, and where. The Map of Knowledge goes into these areas with a very good level of understanding. The book also does a great job laying out the cycle of life for advanced learning and libraries in each of the regions and progressions through time. One of the common cycles that causes the downfall in many regions was gap in the civilization between those with advanced knowledge and learning and those in power, as well as regular poeple. That chasm between the advanced and those not caused a lot of friction, most often leading to the destruction of libraries and institutions. Many of the civilizations never returned to anything close to the advancements. But, the libraries and learning institutions dispersed and found new benefactors and locations to continue moving forward.

Violet Moller has certain given me a good foundation to learn more.

Gillian Tett’s Anthro-Vision was a book, well a chapter in that book, I’ve been waiting for for many years. The chapter on “Financial Crisis” where Tett had been researching financial markets using her background as an anthropologist for a new role at The Financial Times. Tett followed the paths of understanding in the way a good ethnographer / anthropologist does looking to understand the quiet, and seemingly foundational, areas that seem to be out of focus. This area was that of credit swaps in financial loan markets, which were what caused the 2007 housing market collapse and in 2008 at the massive meltdown of the financial markets. The model for building understanding is one that should be common, but sadly isn’t. The remainder of the book is quite good as well.

Productivity

The biggest thing around productivity is my use of Obsidian continues, as mentioned above. In a couple chats recently I have found other have brought up the backlinking / crosslinking as the most valuable feature. For those of us who have been using Macs for a while we find it reminiscent of not only wikis and their power, but in particular VooDoo Pad, which was light weight and everything was easily interlinked and backlinked and search was incredibly good. VooDoo Pad ran locally on your Mac (eventually it also could sync and run on iOS devices, but it needed a special application to run it). The genius bit about Obsidian is it is just markdown notes with an app that acts as an over watcher to connect and index things, but leaves the markdown notes fully usable by any other app or service that can use Markdown.

Having been taking notes in one directory (and its sub-directories) for some 20 years the ability to always get to my notes and use them is highly valuable. I have run through numerous other apps (particularly cloud based) that just die or go away as they are no longer popular or the owners have the wonderfully tragic combination of being ignorant and arrogant. I can pick-up any of my notes in markdown that have backlinks and they also function in Drafts or other programs. The principle of Small Apps Loosely Joined still has resonance and deep value.

Along with Obsidian and the backlinked notes, I have also been keeping a keen eye on Digital Gardening (Maggie Appleton explains this really well and had links to others also diving deeply). At some point I also stumbled upon Software for your second brain - The Stack Overflow Podcast with Alexander Obenauer talking about his quest for creation of a “personal operating system”, which he shares out in his Lab Notes. Much of Alexander’s quest became refocussed on Obsidian as it was doing a lot of what he needed and was trying to frame out so to build it. He has crated extensions to Obsidian to close some of his perceived gaps, but the underlying principle is data portability and a concept incredibly close to the Small Apps Loosely Joined.
3 October 2020

Rebuilding My Note Taking and Management System and Model

The past many weeks I have been digging into a better note taking and management method, while also embracing what I have and my core underlying principles. A continual genre in YouTube I watch is around productivity, particularly around personal knowledge management methods and tools. A couple years back I ran into Zettelkasten Method, that comes from Niklas Luhmann, which focuses on his prolific reading and his card catalogue and related note taking system. Then a few months back I heard Jorge Arango’s interview with Beck Tench it drew Zettelkasten back into focus. The interview with Beck focussed on Tinderbox, which I love, but I also want mobile access to my notes from phone and tablet.

Early Exploration

I have been using Notion a little bit, but my only use the last few months is as an interstitial capture for YouTube and some other rich media. [I like Notion and it seems like a modern take on Podio and has a similar downfall of not sorting out an adaptive data structure for interoperability and consistency.] But, the communities that are interested in Notion became obsessed with Roam Research, so I looked at Roam. Roam and Notion are two vastly different approaches, which can complement each other but in to way replace each other. But, each has a similar faults, no API, no standard export for structured information, and fully cloud based. That is too many common failure points wrapped into one product (Notion is working on and API, which is really good). Roam bugged me most because it relies on an outline format but has no clue about OPML exporting, but worse has no good export model. The cloud based, which requires being connected and online is a model I really don’t like as, particularly if their isn’t a local sync nor standard data format model. What I really like about Roam is its block focussed format, that is akin to purple numbers model of small chunks that are addressable and reusable.

In this time of looking what a next generation of quick note taking would look like, but long used tool, NValt failed spectacularly, in that it would not find my directory where my 1,200+ notes were stored, nor could I add new notes. Fortunately all of my notes are in plain markdown text files, so all I was missing was my tagging of the files in NValt (Brett Terpstra who created NValt has been working on a new tool that can replace NValt but has been taking forever to show up and my need became immediate). This is one of the common reasons for owning my own notes and having them locally and not using somebody else’s model and framework. But, also using the [small apps loosely joined] model where many tools pointing at well formatted / structured data / information can function to their best ability and can use their strengths without breaking anything with the information / data.

Seriously Looking at Note Taking and Management Tools

I started looking at about five or six different note taking tools. I was building out a rough attribute model of tools to help see what each offered or didn’t. I am needing to write this up, but it started with watching Mike and Matty’s, Notion vs Roam vs Obsidian vs Remnote - How to best fit note taking app for you and using their criteria as a base, then building on it. Obsidian and Remnote were already on my list, but also included Zettelnote, Zettlr, and a couple that extended Tidlywiki for a Zettelkasten type model. I also included OmniOutliner as that has been (and will be) my core outlining tool that interplays well with OPML and I can back and forth with good mind mapping tools that also output and import OPML data standard. I also included DevonThink Pro as it is my long used (since 2005) note and information storage and smart search tool (it already was indexing my notes directories) that there is no chance I’m going to give up, but also knew it didn’t have the core functionality I was seeking, wiki-style back linking.

I did a quick test or Roam and ruled it out as it broke rules I try not to break, and it broke many of them (biggest one is know now you are going to exit before you enter anything and a lack of any structure nor API made it a giant risk I’ve been burned by too many times, but the developers have a lot of arrogance about their approach that far too often leads to disasters - sometimes the kindest, smartest, and solid planning people end up with disasters that I feel very badly about but arrogance and ignorant I don’t).

Zettlr and Remnote were next. But the setup took a bit more of me managing and building things and I know when I lose focus those may not be best choices for myself (my past self 15 years ago or more would have loved it and done well with it, but those days are not now).

Obsidian Ticks the Right Boxes and Adapts to My Existing Model

Obsidian is where I put some time. I pointed its “Vault” to my notes directory (and sub-directory) where I had my 1,200 markdown notes already (some of them were .txt extensions, which I did bulk extension swap on) and it could read everything perfectly. One of my first tests was adding backlinks to some of my social lenses and social scaling notes, which worked really well by making related elements connected. I started capturing my notes about what I was doing in Obsidian and the ease of not only connecting things with backlinks, but having the ability to set empty node wiki links (many notes with the same link to a note / page that doesn’t exist yet, but have the same link to it) and then being able to use backlink following from that non-existent notes link list of things pointing to it was insanely valuable.

I have quite a few book list and book note pages already and I started linking them and linking authors and making author pages. I also found I was wanting note page templates for simple book pages in a Zettelkasten model, a book notes template, author / creator template, and a few others. I created these from existing structured notes I’ve used for years and put the outlines in TextExpander using a simple input line or two to label all of the headers with author name or other name.

I started typing out my notes and highlights from books I’ve read and annotated over the years and after the first three or so books I was deeply hooked.

The Use Where Obsidian Showed I was Hooked

Where I knew I was sold was this last weekend I went back to one of Matt Webb’s blog posts on Small Groups that is dense and has links out to great resources. I captured my initial notes on Matt’s post, and annotated relating to his sections. But, I also quickly dug through the linked materials and created and filled out structured note pages for those as well. The James Mullholland post on Small Groups was fantastic and it spidered out to more related resources, so I followed those and took notes. All of this was cross-linked and back-linked and fleshed out small group notes that I have been building as part of social scaling I’ve been writing on and presenting (talks and workshops) for years. The small group size they focus on is roughly team size, but not a team. Both of these are cooperative social models, which scale from teams, groups (small to large groups with similar social interaction models, but the dynamics shift quite a bit around 75 people and break fully about 300 to 500 people), community (everybody inside a firewall or inside an walled off construct), and network (inside and outside a firewall - so for business it is customers, contractors, consultants, vendors, etc. where there needs to be a safe model for sharing information with shared goals as different roles with their purpose come together for back and forth exchange) - more can be found in my related write-up 5 Core Insights for Community Platforms Today.

This note taking and contextualizing and cross linking to rip through and gut a series of related and interrelated pieces has been something I’ve long looked for and wanted. Many dog years ago in college I took reading notes on note cards with citations and context. When writing a paper / essay I would assemble the note cards in an order that could tell a story. Then I would build an outline in WordStar and type in the quotes. Then I would write the narrative and wrapper. Obsidian is starting to get at that, but ripping through a resource to pull out highlights, quotes, annotations, and notes is utterly fantastic. It gives me a solid resource to easily pull together ideas and supporting information.

Other Obsidian Capabilities

Obsidian can show two note pages at once so to easily copy book citation information from the structured book note file into the book note page. The multiple notes in panels also works well for copying quotes to quote pages and cross linking.

Using Obsidian and Still Working from Mobile and Tablet

The mobile use essential had been broken for a bit after Dropbox stopped supporting softlinks in Mac and requiring that to be native in Dropbox and doing the softlink from the Mac to Dropbox. I moved the directory to Dropbox, which leaves a copy locally usable should something happen to Dropbox and added a softlink for local backups. I pointed DevonThink to this directory to index and I was back running. Now I can use Drafts to take a quick note from my iOS devices and push it to the notes directory (later go back and fix the file name) and I have good inbound notes and can use backlinks (which I test later). This method also works for share sheet to Drafts from Overcast or YouTube and having the link to the media and the notes all pulled in.

Happiness with notes has been missing for a while, perhaps happiness has returned.

Resources


7 July 2018

The Sidebar is the New Back Bar

Back in the days when I had time to hangout with friends for drinks, many places had a “back bar” that was more quiet and private.

I haven’t been in the habit of posting here as much as I used to, but I still am putting things into Pinboard and somethings I flag with “linkfodder”, which is my relatively unique tag to pull out favorites. I use the API from Pinboard to pull the linkfodder tagged items into the sidebar here. Occasionally I annotate them and that is brought here as well. This sidebar mini blog feels sort of like the back bar, which is a little more quiet and calm and you can see some things of interest to me (if that is of interest to you) and track them down.


3 December 2016

Diffen for Comparisons

I stumbled across Diffen the other day thanks to Macdrifter’s Diffen mention. I have found it a great service for comparing things. But keep thinking of all the things I really want it to compare, but since it has two fields that allow you to compare any two things you can do it. I may keep the Diffen compares Holland vs Netherlands close at hand as it is a pet peeve and explaining it isn’t quite as easy as pointing to the link (particularly when people say, “well everybody calls it Holland”, the answer is everybody doesn’t and understanding what is correct is easy).


1 January 2016

Happy New Year - 2016 Edition

Happy New Year!

I’m believing that 2016 will be a good year, possibly a quite good year. After 7 years of bumpy and 2015 off to a rough start on the health front it stayed rather calm.

I don’t make resolutions for the new year. It is a practice that always delayed good timing of starting new habits and efforts when they were better fits. The, “oh, I start doing this on on New Years” always seemed a bit odd when the moment something strikes you is a perfectly good moment to start down the path to improvement or something new.

This blog has been quiet for a while, far too long in fact. Last year when I was sick it disrupted a good stretch of posting on a nearly daily basis. I really would like to get back to that. I was planning to start back writing over the past couple weeks, but the schedule was a bit filled and chaotic.

Digging Through Digital History

This past year I did a long stretch working as expert witness on a social software case. The case was booted right before trial and decided for the defense (the side I was working with). In doing this I spent a lot of time digging back through the last 5 to 10 years of social software, web, enterprise information management, tagging / folksonomy, and communication. Having this blog at my disposal and my Personal InfoCloud blog were a great help as my practice of knocking out ideas, no matter how rough, proved a great asset. But, it also proved a bit problematic, as a lot of things I liked to were gone from the web. Great ideas of others that sparked something in me were toast. They were not even in the Ineternet Archive’s Wayback Machine. Fortunately, I have a personal archive of things in my DevonThink Pro repository on my laptop that I’ve been tucking thing of potential future interest into since 2005. I have over 50,000 objects tucked away in it and it takes up between 20GB to 30GB on my hard drive.

I have a much larger post brewing on this, which I need to write and I’ve promised quite a few others I would write. The big problem in all of this is there is a lot of good, if not great, thinking gone from the web. It is gone because domains names were not kept, a site changed and dropped old content, blogging platforms disappeared (or weren’t kept up), or people lost interest and just let everything go. The great thinking from the 90s that the web was going to be a repository for all human thinking with great search and archival properties, is pretty much B.S. The web is fragile and not so great at archiving for long stretches. I found HTML is good for capturing content, but PDF proved the best long term (10 years = long term) digital archive for search in DevonThink. The worst has been site with a lot of JavaScript not saved into PDF, but saved as a website. JavaScript is an utter disaster for archiving (I have a quite a few things I tucked away as recently as 18 months ago that are unreadable thanks to JavaScript (older practices and modifications which may be deemed security issues or other changes of mind have functional JavaScript stop working). The practice of putting everything on the web, which can mean putting application front ends and other contrivances up only are making the web far more fragile.

The best is still straight up HMTL and CSS and enhancing from there with JavaScript. The other recent disaster, which is JavaScript related, is infinite scroll and breaking distinct URLs and pages. Infinite scroll is great for its intended use, which is stringing crappy content in one long string so advertisers see many page views. It is manufacturing a false understanding that the content is valued and read. Infinite scroll has little value to a the person reading, other than if the rare case good content is strung together (most sites using infinite scroll do it because the content is rather poor and need to have some means of telling advertisers that they have good readership). For archival purposes most often capturing just the one page you care about gets 2 to 5 others along with it. Linking back to the content you care about many times will not get you back to the distinct article or page because that page doesn’t actually live anywhere. I can’t wait for this dim witted practice to end. The past 3 years or so of thinking I had an article / page of good content I could point to cleanly and archive cleanly was a fallacy if I was trying to archive in the playland of infinite scroll cruft.

Back to Writing Out Loud

This past year of trying to dig out the relatively recent past of 5 to 10 years with some attempts to go back farther reinforced the good (that may be putting it lightly) practice of writing out loud. In the past few years I have been writing a lot still. But, much of this writing has been in notes on my local machines, my own shared repositories that are available to my other devices, or in the past couple years Slack teams. I don’t tend to write short tight pieces as I tend to fill in the traces back to foundations for what I’m thinking and why. A few of the Slack teams (what Slack calls the top level cluster of people in their service) get some of these dumps. I may drop in a thousand or three words in a day across one to four teams, as I am either conveying information or working through an idea or explanation and writing my way through it (writing is more helpful than talking my way through it as I know somebody is taking notes I can refer back to).

A lot of the things I have dropped in not so public channels, nor easily findable again for my self (Slack is brilliantly searchable in a team, but not across teams). When I am thinking about it I will pull these brain dumps into my own notes system that is searchable. If they are well formed I mark them as blogfodder (with a tag as such or in a large outline of other like material) to do something with later. This “do something with later” hasn’t quite materialized as of yet.

Posting these writing out loud efforts in my blogs, and likely also into my Medium area as it has more constant eyes on it than my blogs these days. I tend to syndicate out finished pieces into LinkedIn as well, but LinkedIn isn’t quite the space for thinking out loud as it isn’t the thinking space that Medium or blogs have been and it doesn’t seem to be shifting that way.

Not only have my own resources been really helpful, but in digging through expert witness work I was finding blogs to be great sources for really good thinking (that is where really good thinking was done, this isn’t exactly the case now, unless you consider adding an infinitely redundant cat photo to a blog being really good thinking). A lot of things I find valuable still today are on blogs and people thinking out loud. I really enjoy David Weinberger, Jeremy Keith, and the return of Matt Webb to blogging. There are many others I read regularly (see my links page for more).


2 December 2014

30 Days Had November

Well the attempt to blog every day in November didn’t get as much wind in its sails as I had hoped it would have. November had 30 days, but I had far fewer posts than 30. I didn’t get a new habit set. But, I am not yet deterred as I am keeping this attempt going.

One of the things I’ve thought about doing is doing a weekly link dump of items I found of interest through out the week. These are some of my favorite week end reads when I curl up with the laptop (or iPad), a cup of coffee and a blanket. I have long been a fan of Om’s weekend delivery of his 5 (or 7) things to read this weekend as they are nearly always high quality, in depth, and decent (meaning on the longer side) length. I’ve also grown to head toward Josh Ginter of “The Newsprint” weekly “The Sunday Edition” link dump of the week. Recently Michael Sippy has been back sharing on the web (just like the days of yore) and his Filtered Week series on Medium is an annotated link list gem.

One of the reasons I have been considering this (and actually tucking links away for posting) is the past few weeks I realized my blog’s link list on the side of this blog that was posted from Delicious is now dead and gone. The link roll that was a staple of Delicious from 2004 or so was nuked with many other helpful features and functionality that kept Delicious as one part of my workflow. I moved most of my social bookmarking to Pinboard a few years back, but I still fed Delicious and then Delicious fed Pinboard. Well, that was the case until the new owners of Delicious (sadly Delicious gets passed around the IT community like a hot potato with each new owner thinking they are going to update it and improve it, yet lack a rat’s clue of the basics nor how to keep (now kept) the workings that underpin many parts of the web running) fumbled things and Pinboard stopped automatically ingesting Delicious. I really missed the change at Pinboard (was heads down on a project when that happened), but now all my social bookmarking is happening there.

The lack of a link sidebar is the push to share things that I find as gems from the week. I could repoint the Delicious javascript to Pinboard, but Pinboard also captures all my starred / favorited items (I don’t use starring in Twitter as a favorite, but more of a hook for things to hold on to and / or come back to) and things favorited in Instagram, and imports from other services. Pinboard, because I use the paid archive service is an endpoint that serves also as a place to do full text search of the items bookmarked there. Until I can sort out a good filter or means of tagging in my workflow, I am keeping the link list off the sidebar. But, in its place I am likely going to do a weekly link list.


2 May 2012

The Data Journalism Handbook is Available

The Data Journalism Handbook is finally available online and soon as the book Data Journalism Handbook - from Amazon or The Data Journalism Handbook - from O’Reilly, which is quite exciting. Why you ask?

In the October of 2010 the Guardian in the UK posted a Data Journalism How To Guide that was fantastic. This was a great resource not only for data journalists, but for anybody who has interest in finding, gathering, assessing, and doing something with the data that is shared found in the world around us. These skill are not the sort of thing that many of us grew up with nor learned in school, nor are taught in most schools today (that is another giant problem). This tutorial taught me a few things that have been of great benefit and filled in gaps I had in my tool bag that was still mostly rusty and built using the tool set I picked up in the mid-90s in grad school in public policy analysis.

In the Fall of 2011 at MozFest in London many data journalist and others of like mind got together to share their knowledge. Out of this gathering was the realization and starting point for the handbook. Journalists are not typically those who have the deep data skills, but if they can learn (not a huge mound to climb) and have it made sensible and relatively easy in bite sized chunk the journalists will be better off.

All of us can benefit from this book in our own hands. Getting to the basics of how gather and think through data and the questions around it, all the way through how to graphically display that data is incredibly beneficial. I know many people who have contributed to this Handbook and think the world of their contributions. Skimming through the version that is one the web I can quickly see this is going to be an essential reference for all, not just journalists, nor bloggers, but for everybody. This could and likely should be the book used in classes in high schools and university information essentials taught first semester first year.


30 March 2011

Late to Realizing Ovi Maps Does Exactly What I Wish

I been a big fan of Nokia's mapping solution built into its smart phones, Ovi Maps as it provides the best mobile turn by turn directions I've seen on any mobile device. But, this is largely because Nokia owns Navteq, which has long been the leader for on board mapping and driving solutions.

That FINALLY! Moment Reached

While I have been incredibly impressed with the Ovi mapping on my Nokia E72 device and often use the Ovi resources on the web, I hit that finally, somebody got this right moment with Ovi over the weekend. While, many web mapping solutions allow you to save favorites on the web getting those to sync to your mobile device, with your directions has been left out of most of these solutions (I have been complaining to friends at Google, Yahoo, and elsewhere for many years that this is a no-duh next step). Well, it seems Ovi figured this out quite a while back. (I noticed Google Mobile Maps provided this at the end of 2009, but have never been able to get it to work, even on my supported Symbian device.)

The simplicity and ease with with Nokia's Ovi pulls this off is rather stunning. With this aha moment, I feel like I was the last one to see this and sort it out, but in chats with other mobile maps and navigation users, they have been pained waiting for exactly this functionality, as most people it seems will get a location link and add it to their desktop maps (particularly for travel) but that does them little good as they don't take their desktop or open laptop into the car with them, they take their mobile. Understanding context of use is incredibly valuable.

Now may be a good time to check your device's capability, although iPhone does not seem to have this functionality supported by Google maps (surprised?).


31 December 2010

Closing Delicious? Lessons to be Learned

There was a kerfuffle a couple weeks back around Delicious when the social bookmarking service Delicious was marked for end of life by Yahoo, which caused a rather large number I know to go rather nuts. Yahoo, has made the claim that they are not shutting the service down, which only seems like a stall tactic, but perhaps they may actually sell it (many accounts from former Yahoo and Delicious teams have pointed out the difficulties in that, as it was ported to Yahoo’s own services and with their own peculiarities).

Redundancy

Never the less, this brings-up an important point: Redundancy. One lesson I learned many years ago related to the web (heck, related to any thing digital) is it will fail at some point. Cloud based services are not immune and the network connection to those services is often even more problematic. But, one of the tenants of the Personal InfoCloud is it is where you keep your information across trusted services and devices so you have continual and easy access to that information. Part of ensuring that continual access is ensuring redundancy and backing up. Optimally the redundancy or back-up is a usable service that permits ease of continuing use if one resource is not reachable (those sunny days where there's not a cloud to be seen). Performing regular back-ups of your blog posts and other places you post information is valuable. Another option is a central aggregation point (these are long dreamt of and yet to be really implemented well, this is a long brewing interest with many potential resources and conversations).

With regard to Delicious I’ve used redundant services and manually or automatically fed them. I was doing this with Ma.gnol.ia as it was (in part) my redundant social bookmarking service, but I also really liked a lot of its features and functionality (there were great social interaction design elements that were deployed there that were quite brilliant and made the service a real gem). I also used Diigo for a short while, but too many things there drove me crazy and continually broke. A few months back I started using Pinboard, as the private reincarnation of Ma.gnol.ia shut down. I have also used ZooTool, which has more of a visual design community (the community that self-aggregates to a service is an important characteristic to take into account after the viability of the service).

Pinboard has been a real gem as it uses the commonly implemented Delicious API (version 1) as its core API, which means most tools and services built on top of Delicious can be relatively easily ported over with just a change to the URL for source. This was similar for Ma.gnol.ia and other services. But, Pinboard also will continually pull in Delicious postings, so works very well for redundancy sake.

There are some things I quite like about Pinboard (some things I don’t and will get to them) such as the easy integration from Instapaper (anything you star in Instapaper gets sucked into your Pinboard). Pinboard has a rather good mobile web interface (something I loved about Ma.gnol.ia too). Pinboard was started by co-founders of Delicious and so has solid depth of understanding. Pinboard is also a pay service (based on an incremental one time fee and full archive of pages bookmarked (saves a copy of pages), which is great for its longevity as it has some sort of business model (I don’t have faith in the “underpants - something - profit” model) and it works brilliantly for keeping out spammer (another pain point for me with Diigo).

My biggest nit with Pinboard is the space delimited tag terms, which means multi-word tag terms (San Francisco, recent discovery, etc.) are not possible (use of non-alphabetic word delimiters (like underscores, hyphens, and dots) are a really problematic for clarity, easy aggregation with out scripting to disambiguate and assemble relevant related terms, and lack of mainstream user understanding). The lack of easily seeing who is following my shared items, so to find others to potentially follow is something from Delicious I miss.

For now I am still feeding Delicious as my primary source, which is naturally pulled into Pinboard with no extra effort (as it should be with many things), but I'm already looking for a redundancy for Pinboard given the questionable state of Delicious.

The Value of Delicious

Another thing that surfaced with the Delicious end of life (non-official) announcement from Yahoo was the incredible value it has across the web. Not only do people use it and deeply rely on it for storing, contextualizing links/bookmarks with tags and annotations, refinding their own aggregation, and sharing this out easily for others, but use Delicious in a wide variety of different ways. People use Delicious to surface relevant information of interest related to their affinities or work needs, as it is easy to get a feed for not only a person, a tag, but also a person and tag pairing. The immediate responses that sounded serious alarm with news of Delicious demise were those that had built valuable services on top of Delicious. There were many stories about well known publications and services not only programmatically aggregating potentially relevant and tangential information for research in ad hoc and relatively real time, but also sharing out of links for others. Some use Delicious to easily build “related information” resources for their web publications and offerings. One example is emoted by Marshall Kirkpatrick of ReadWriteWeb wonderfully describing their reliance on Delicious

It was clear very quickly that Yahoo is sitting on a real backbone of many things on the web, not the toy product some in Yahoo management seemed to think it was. The value of Delicious to Yahoo seemingly diminished greatly after they themselves were no longer in the search marketplace. Silently confirmed hunches that Delicious was used as fodder to greatly influence search algorithms for highly potential synonyms and related web content that is stored by explicit interest (a much higher value than inferred interest) made Delicious a quite valued property while it ran its own search property.

For ease of finding me (should you wish) on Pinboard I am http://pinboard.in/u:vanderwal

----

Good relevant posts from others:


This work is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike License.